Did Microsoft leak the number of parameters in ChatGPT?
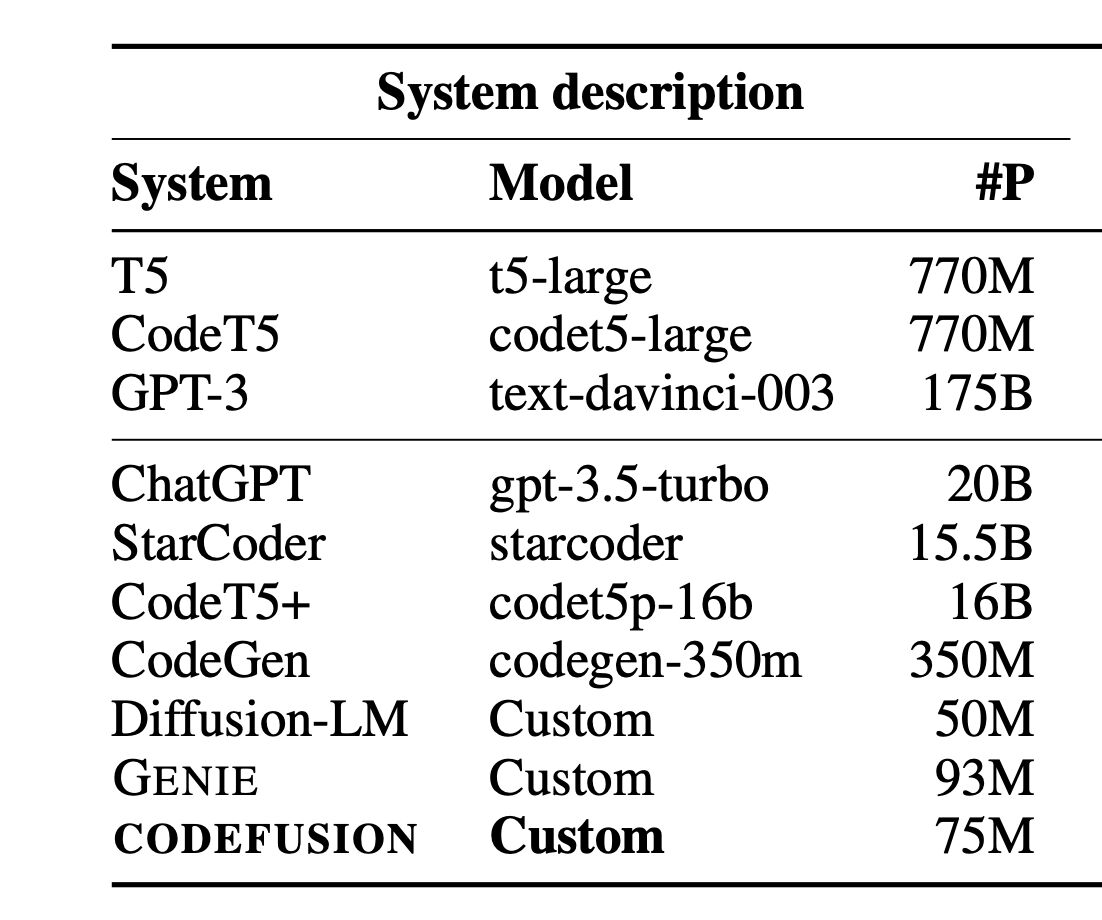
A Microsoft publication is causing quite a stir because it appears to have leaked the number of parameters in GPT-3.5 Turbo, which would be 20 billion (20B). This seems rather "small" compared to the very large language models today like Falcon (180B), LLama-2 (70B), etc.
As a reminder, Microsoft is a partner of OpenAI so they certainly have access to this kind of information.
Some think this is a typo and the real number would be closer to 200B, because its bigger brother GPT-3 has 175B parameters.
But when you think about it, there are a number of clues pointing towards the 20B figure:
▶ The GPT-3.5 Turbo API is 10 times cheaper than Text-Davinci-003 (175B). By proportionality, we would arrive at around 20B.
▶ Sam Altman stated last April "I think we're at the end of the era where it's going to be these, like, giant, giant models [...], we'll make them better in other ways."
▶ Models like Mistral (7B) have shown it's possible to do better with fewer parameters.
We already knew, thanks to the famous "Chinchilla" publication, that most LLMs were suboptimal. But if it turns out that GPT-3.5 Turbo really has 20B parameters, it would open up some very interesting possibilities since we can already run 13B LLMs on MacBooks.
How did they do it? We can speculate on elements like knowledge distillation, pruning, longer training times, and above all drastically improving the quality of the training data...
GPT-3.5-Turbo launched in March 2023, so if all of this is confirmed, it would mean OpenAI still has a huge lead over its competitors in terms of know-how.
paper: https://arxiv.org/pdf/2310.17680.pdf